
ECHELEN PASS90: Knowing What Not to Compute

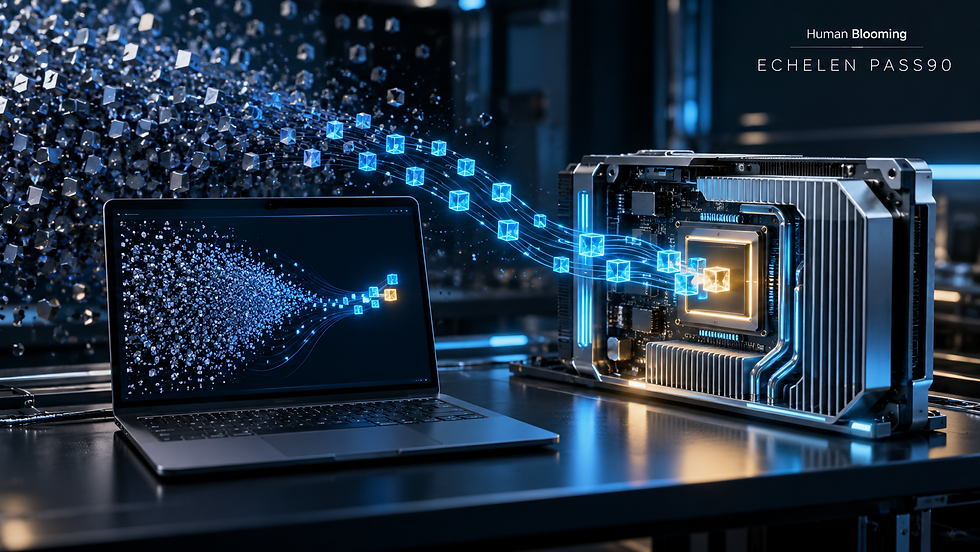
A public demonstration of exact candidate optimization: the blind path scores 128 million candidates; ECHELEN directly addresses 62,500, avoids 127,937,500 heavy evaluations, and reaches the same winner and score.
ANALYSIS · GPU · WORK AVOIDANCE · CANDIDATE OPTIMIZATION · PUBLIC EVIDENCE
PASS90 is not Human Blooming’s speed demonstration. It demonstrates something that comes earlier: when the structure of a problem makes it possible to know exactly where the answer can be, an enormous amount of computation can cease to exist before heavy scoring. |
For decades, the performance conversation has revolved around one question: how to perform more operations per second. More cores, more parallelism, more bandwidth, more efficient kernels, and increasingly powerful accelerators.
ECHELEN PASS90 introduces an earlier question: how many of those operations need to exist at all?
That distinction completely changes how the experiment should be read. The most striking figure — a mean 543.1528× wall-clock speedup across three consolidated runs — is not the mechanism. It is a measured consequence of reducing the heavy problem exactly from 128,000,000 candidates to 62,500 before running the same scoring function.
Within Human Blooming’s broader research campaigns, PASS90 is a deliberately bounded piece of work. It is not intended to summarize the company’s entire research program. Precisely for that reason, its methodological and conventional-product significance may be disproportionate to its size: it isolates an idea, freezes it in code, runs it on commercial NVIDIA hardware, requires the result to be preserved, and publishes an Evidence Pack for inspection.
HEAVY WORK | EXPLICIT STRUCTURE | OBSERVED TIME | CORRECTNESS |
2048× less | ≈1024× less | 516.49×–561.78× | Same winner and score |
1. The Real Result: Knowing Where Not to Search
Imagine two systems facing the same universe of 128 million candidates and the same computationally heavy evaluation function. The first scores the entire space and filters afterward. The second knows an exact property of the problem that allows it to construct directly the set in which the solution can be found.
The first must submit 128,000,000 candidates to heavy scoring. The second needs only 62,500. The difference is 127,937,500 candidates that no longer require that evaluation.
For every candidate ECHELEN scores, the blind path also scores another 2,047 that, by the exact definition of the gate, cannot belong to the valid subspace.
Then comes the decisive point: the winner is still there. All three consolidated runs record best_index=119,418,898 and best_score=425.7733459472656. This is not an approximate answer or a similar candidate; it is the same consolidated winner produced by the full blind calculation.

2. It Was Not Filtered Afterward; It Was Addressed Beforehand
One distinction is essential. PASS90 does not demonstrate a filter that must first traverse all 128 million candidates in order to decide quickly which ones to discard. The addressable path constructs the valid indices directly.
Both paths use the same heavy function, echelen_score(i, heavy_iters, seed). GPU_RAW_BLIND_FULL runs it across every index i∈[0,N) and then applies the validity condition. GPU_QPE_ADDRESSABLE_GATE constructs i = residue + j×gate_mod and runs the same scoring only on those indices.
For N=128,000,000, gate_mod=2048, and residue=18, valid_n=62,500. The optimization occurs before heavy scoring.
This is a crucial distinction in any product discussion: the goal is not to build an ultra-fast filter that examines the entire universe, but to exploit enough structure to address the useful universe directly without asking the expensive computation about everything else.
3. The Reduction Is Exact, Not Probabilistic
The condition i % 2048 == 18 defines the valid domain exactly. There is no model estimating which candidates appear promising. There is no confidence threshold. No accuracy is sacrificed in order to discard candidates.
The addressable path mathematically enumerates the same set that the baseline recognizes only after scoring the entire space.
That is why PASS90 should not be confused with probabilistic pruning. Within the benchmark definition, an excluded candidate is not merely unlikely; it cannot belong to the valid subspace.
This is probably one of the experiment’s strongest properties. Eliminating work is easy if one accepts the risk of eliminating useful information. The difficult part is proving which work can disappear without making the answer disappear with it.
4. 2048× Less Heavy Scoring
The baseline scores 128,000,000 candidates. ECHELEN/QPE scores 62,500. The ratio is exactly 2048:1.
With heavy_iters=1024 on both paths, the heavy core drops from 131,072,000,000 to 64,000,000 iterations. Again, 2048×.
The avoided fraction is 99.951171875%. Unlike a timing result, this percentage is structural: it follows from the published parameters and does not depend on temperature, GPU clock speed, or system load.
The number that explains PASS90 is not 543. It is 2048. The 543.15× figure comes later, when a real GPU converts part of that algorithmic reduction into real-world elapsed time.

5. The Winner Always Remains Inside the Addressed Space
PASS is not awarded on speed alone. The benchmark requires correct_result=True and speedup≥90×. After each run, it performs argmax, retrieves best_index and best_score, and checks result compatibility.
The consolidated winner, 119,418,898, satisfies the gate exactly: 119,418,898 mod 2048 = 18. Its position is j=(119,418,898−18)/2048=58,310, within the 62,500 valid elements.
Across all three recorded runs, the consolidated result is the same. This links three properties that should not be separated when telling the story: extreme reduction, real acceleration, and preservation of the result.
Eliminating 99.951% of the scoring is valuable only because the winning candidate is not eliminated.
Eliminating 99.951% of the scoring is valuable only because the winner is not eliminated. |
6. ≈1024× Less Principal Explicit Structure
The effect does not end with the number of candidates. The baseline allocates scores with 128,000,000 float32 elements: 512,000,000 bytes, approximately 488.281 MiB.
The addressable path allocates valid_scores and valid_indices, each with 62,500 four-byte elements: 500,000 bytes combined, approximately 488.281 KiB.
For those explicitly allocated structures, the ratio is 1024×. It should not be described as 1024× less total GPU memory: the runtime, CuPy, argmax, and other components add memory consumption. The evidence does support ≈1024× fewer bytes in the principal output/intermediate structures visible in the benchmark.
7. Speed Is the Physical Consequence
The three consolidated runs record speedups of 516.4896×, 561.7751×, and 551.1938×. The minimum is 516.4896×; the mean, 543.1528×; the median, 551.1938×; and the maximum, 561.7751×.
The PASS90 threshold is 90×. Even the weakest run exceeds it by approximately 5.74 times; the mean exceeds it by approximately 6.04 times.
The ideal structural factor is 2048×. The observed speedups realize approximately 25.22% to 27.43% of that reduction, with a mean near 26.52%. Launch, reduction, argmax, synchronization, and retrieval costs remain.
That makes the result more credible, not less. The observed speedup is enormous, but not magical: it is the partial physical translation of an even larger algorithmic reduction.
8. The Clock Runs Until a Verifiable Winner Is Available
The code records CUDA events for kernel timing, but the official speedup is calculated from elapsed_s using time.perf_counter(). That interval includes the kernel, argmax, index retrieval, score retrieval, and synchronization.
The official comparison therefore does not isolate only the most favorable portion of a kernel; it measures the time until the result required to verify the winner is available.
The benchmark performs a warm-up and uses repeat=3, retaining the lowest elapsed_s for each path. This is a best-of-three policy and should be stated as such. It is not the mean or median of the three internal timings.
9. What This Means for a Computing Platform
A computing platform has finite resources: GPU time, memory, bandwidth, energy, thermal capacity, infrastructure, and cost. Traditional engineering seeks to extract more performance from those resources.
PASS90 points to a complementary layer. If the problem makes it possible to know in advance which fraction can affect the result, the platform does not need to spread its capacity across both relevant and irrelevant work.
The economic question is no longer only how many operations the GPU can perform per second. Another question emerges: what percentage of the operations we are about to ask it to perform actually need to exist?
PASS90 does not answer that question for every workload. It demonstrates a controlled case in which the answer is exact: only 1 out of every 2,048 candidates requires heavy scoring. And it makes it possible to measure what happens when that information is used before CUDA. We also know that Human Blooming has demonstrated this on multiple occasions and in real-world work that the company plans to publish later.

10. NVIDIA Is Not the Adversary; It Is the Computing Resource
The NVIDIA GeForce RTX 5090 Laptop GPU is the platform on which we recorded the benchmark. The experimental adversary is GPU_RAW_BLIND_FULL running on the same NVIDIA platform.
It would therefore be incorrect to say that Human Blooming is 543× faster than NVIDIA, that ECHELEN outperforms CUDA, or that PASS90 beats NVIDIA benchmarks. The evidence does not seek to support any of those conclusions.
The more interesting interpretation is complementary: NVIDIA maximizes available computing capacity; QPE/ECHELEN demonstrates, for this benchmark, how to drastically minimize the amount of that capacity that needs to be consumed.
Nor should it be said that NVIDIA certified or validated ECHELEN. What can be demonstrated is that the recorded benchmark uses the stated NVIDIA resource and that the Evidence Pack publishes the corresponding code, parameters, results, and verification mechanisms.
The advantage does not come from winning a FLOPS race against Blackwell; it comes from needing far fewer FLOPS to reach the same result. |
11. A Conventional Product Hypothesis
PASS90 is particularly interesting because it does not require ECHELEN to be presented as a replacement for existing hardware. Its potential product value lies precisely in acting before that hardware.
If an application has enough structure to address the relevant subspace, the GPU’s massive computing power can be reserved for work capable of changing the result.
The benchmark does not demonstrate that other problems will be reduced by 2048× or achieve a 543× speedup, even though Human Blooming has already obtained such results elsewhere. What it does demonstrate publicly is a methodology that can be pursued in other domains: identify structure, turn it into addressing, eliminate work that can be shown to be irrelevant, and measure whether the result is preserved.
This is a particularly useful connection between Human Blooming’s research campaigns and products built on conventional infrastructure.
12. Sectors Where the Question Deserves Investigation
PASS90 does not demonstrate sector-specific applications. But it does make it possible to formulate concrete research hypotheses without attributing results that do not yet exist.
In drug discovery and computational chemistry, the question would be whether known constraints can exclude regions of large candidate spaces before expensive simulations or evaluations. Human Blooming plans to publish an article and a demonstration in this sector shortly, together with the full Evidence Pack, as is its practice.
In engineering and design, the question is whether physical, geometric, or functional constraints can eliminate configurations that cannot satisfy the problem conditions before compute-intensive stages.
In logistics and combinatorial optimization, whether exact constraints can eliminate infeasible regions of the space before expensive evaluation.
In query engines and data processing, whether metadata or structure can avoid moving or processing blocks that cannot contribute to the result.
In scientific simulation, whether invariants, boundary conditions, or other properties can exclude impossible states before expensive numerical computation.
In AI and candidate-based systems, the hypothesis must be treated with particular care: investigate whether there are stages at which certain paths, candidates, or evaluations can be shown to be incapable of affecting the required result before accelerated computing resources are consumed.
In cybersecurity, search, and large-space analysis, the question would be whether demonstrable structural knowledge can reduce the universe subjected to expensive operations without introducing false exclusions.
None of these sectors automatically inherits PASS90’s figures. They are research directions suggested by the principle, not claims demonstrated by this benchmark, although the Human Blooming team is actively demonstrating them in additional work.
13. Work Avoidance as a Hardware Multiplier
If this principle transfers to other structured problems, it would not necessarily compete with more powerful GPUs. It would benefit from them.
More bandwidth would still be useful. Better kernels would still matter. CUDA would continue to optimize execution. An addressing layer would target a different variable: how much work all that infrastructure needs to receive.
In PASS90, the baseline sends 128 million candidates to scoring. ECHELEN sends 62,500. The GPU remains the same extraordinarily powerful tool. What changes is what it is being asked to do.
This is a different way to multiply the useful value of available compute: not by increasing physical FLOPS, but by avoiding their consumption where structure proves they cannot contribute.

14. Three Multipliers and One Condition
PASS90 presents three distinct, linked advantages. First: 2048× fewer candidates and heavy-scoring iterations. Second: ≈1024× fewer bytes in the principal explicit structures being compared. Third: 516.49×–561.78× less observed time, with a mean of 543.15×.
But there is a fourth condition supporting all three: the correct result.
Without preservation of the winner, the first three figures would describe only a reduction in work. With the same winner and a compatible score, they describe optimization within the benchmark.
That is why PASS90 deserves to be read as a chain of evidence rather than as an isolated speed figure.
15. Provenance Is Designed, Too
The Evidence Pack contains more than a results table. It includes frozen CUDA/CuPy code, a machine-readable structured summary, a human-readable replication report, SHA256SUMS, an offline verifier, Windows and Linux/macOS scripts, a claim boundary, and a license.
The public ZIP is committed by SHA-256 995a728ca5e0d616ecba13b2c12269244ef4f6f2fc036599226cd14b79d5a3ad. The extracted package contains 11 files; ten artifacts are covered by SHA256SUMS.txt and verify 10/10.
The published chain can be read as outer SHA-256 → exact ZIP → SHA256SUMS → code/summary/report/verifier → three historical manifest_sha256 commitments. In addition, the benchmark contains build_manifest() and a FINAL_SEAL whose manifest_sha256 seals the manifest.
That makes provenance and auditability explicit parts of the evidence design.
16. The Limitations Increase Credibility
The package does not include the historical raw OUT_PASS90_* directories. The three manifest_sha256 values are historical commitments, but those directories cannot be revalidated byte-for-byte from the public ZIP. They are available under NDA and agreement with the company.
The claim boundary excludes universal 500× acceleration, quantum hardware or quantum advantage, cryptographic breaks, superiority over CUDA, and any interpretation that Human Blooming has outperformed NVIDIA.
These boundaries are not inconvenient footnotes. They are part of the experimental discipline. A narrow, sealed, reproducible claim is harder to discredit than a spectacular but ambiguous assertion.
17. A Small Piece Within a Much Larger Ambition
PASS90 should not be artificially turned into Human Blooming’s definitive campaign. Its strength comes precisely from being a specific experiment within a much broader research effort.
It is conventional in an important sense: a commercial GPU, CUDA/CuPy, a defined problem, a blind baseline, and an addressable path. The reader does not need to accept a promise about future hardware in order to evaluate the mechanism.
That gives it special value as a bridge to product. It allows us to ask which parts of a broader research philosophy can be translated into software and optimization layers that make better use of platforms already deployed.

18. The Real Question PASS90 Leaves Behind
The natural headline is 543×. The structural number is 2048×. But the methodological contribution can be summarized without numbers.
Conventional optimization asks how to execute faster. ECHELEN adds an earlier question: what part of the work needs to exist at all?
Human Blooming is progressively transferring that principle from controlled benchmarks to classes of real-world problems while maintaining correctness, auditability, and measurable reductions. In retrospect, PASS90 will matter not because an RTX 5090 Laptop GPU recorded a mean 543.15× speedup.
It will matter because it showed one idea with exceptional clarity: not winning the race by performing every operation faster, but changing the race by proving which operations never need to be run.
The best GPU operation may be the one the structure of the problem proves no longer needs to be executed. |
Evidence Summary
Benchmark | ECHELEN_PASS_90X_BENCH_V3_ADDRESSABLE_GATE |
Recorded platform | NVIDIA GeForce RTX 5090 Laptop GPU |
Baseline | GPU_RAW_BLIND_FULL |
Addressable path | GPU_QPE_ADDRESSABLE_GATE |
Heavy function | echelen_score(i, heavy_iters, seed) on both paths |
Candidates scored | 128,000,000 → 62,500 |
Candidates without heavy scoring | 127,937,500 |
Heavy iterations | 131,072,000,000 → 64,000,000 |
Structural work avoidance | 99.951171875% |
Principal explicit structures | ≈488.281 MiB → ≈488.281 KiB |
Recorded speedups | 516.4896× · 561.7751× · 551.1938× |
Mean | 543.1528× |
Consolidated winner | best_index=119,418,898 |
Consolidated score | 425.7733459472656 |
Evidence ZIP SHA-256 | 995a728ca5e0d616ecba13b2c12269244ef4f6f2fc036599226cd14b79d5a3ad |
Published integrity | 10/10 covered internal hashes verified |
Editorial Note
This article deliberately distinguishes between results demonstrated by ECHELEN PASS90 and potential future applications. The sector-specific applications described are hypotheses for transfer and research, not results obtained in those sectors.
References to NVIDIA describe the computing platform used and the technical context. They do not imply certification, validation, endorsement, or collaboration by NVIDIA with Human Blooming. PASS90 is a specific benchmark, not a universal performance claim, nor is it intended to be. Different cases have produced different results, but results that have been equally overwhelming.


Comments